Publications
Personalized alignment & safety
Adapting model behavior to users’ literacy, conversational goals, and authorized needs.
-
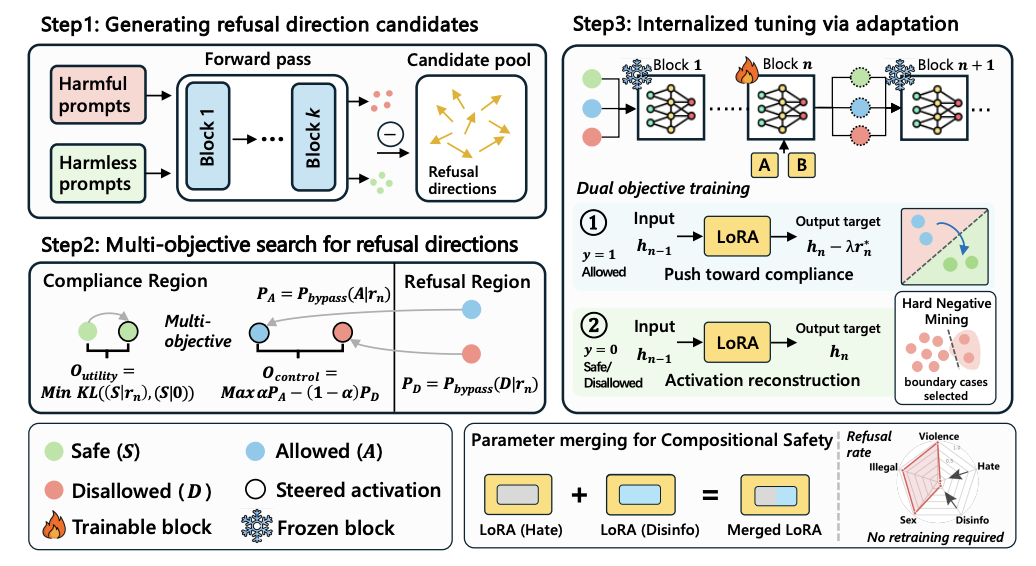
- Problem
- Blanket refusal behavior can block legitimate professional uses of LLMs.
- Contribution
- Palette combines refusal-direction search, lightweight adaptation, and parameter merging for selective, authorized safety control.
- Key Insight
- Domain-specific adaptations can be composed without retraining while preserving safety outside the authorized domains.
-
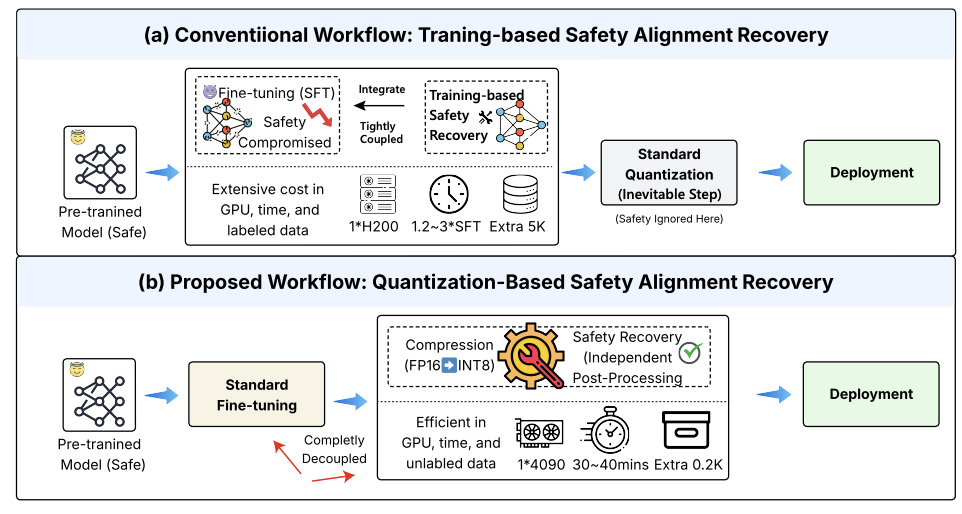
- Problem
- Task-specific fine-tuning can erode safety alignment, making deployment riskier.
- Contribution
- Q-realign restores alignment during quantization, reducing unsafe outputs while preserving task performance.
- Key Insight
- Combining realignment with compression makes safety restoration practical on consumer hardware.
-
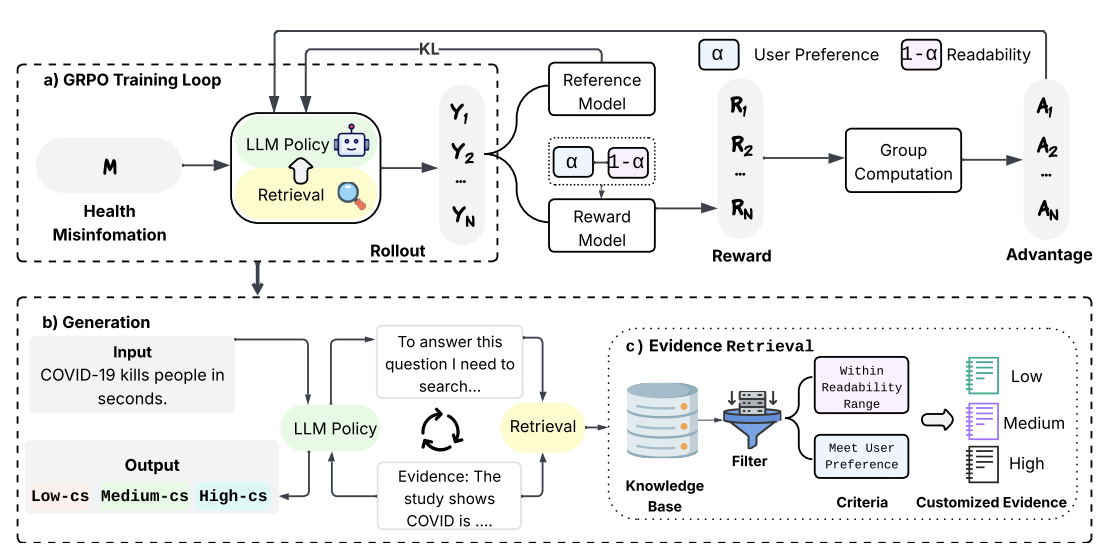
- Problem
- Health misinformation corrections may be too difficult for their intended audience to understand.
- Contribution
- Controlled-Literacy combines retrieval and reinforcement learning to tailor counterspeech to different health literacy levels.
- Key Insight
- Aligning language with audience literacy produces more accessible and preferred responses.
-
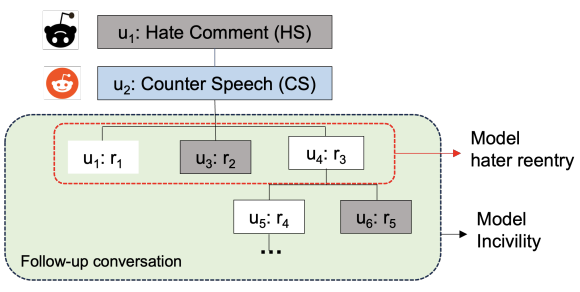
- Problem
- Counterspeech generation should account for what happens next in a conversation.
- Contribution
- Prompting, fine-tuning, and reinforcement learning methods constrained by low incivility and non-hateful hater reentry.
- Key Insight
- Desired conversational outcomes can directly guide generation toward more constructive exchanges.
LLM agents & post-training
Learning dialogue decisions, coordinating evidence and responses, and making model adaptation more efficient.
-
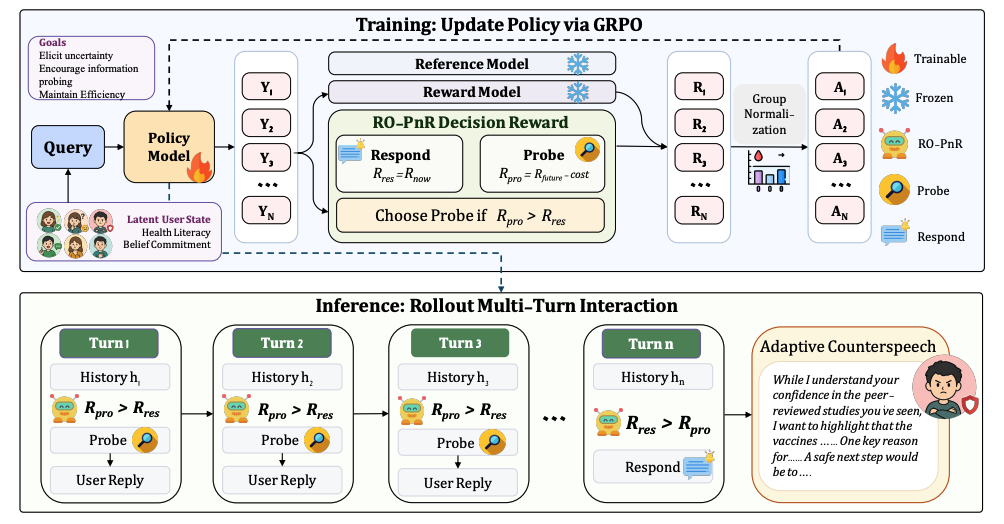
- Problem
- Asking more questions can improve a correction, but also adds interaction cost.
- Contribution
- RO-PnR learns when to probe and when to deliver a final response in health misinformation dialogues.
- Key Insight
- Weighing information gain against interaction cost improves utility with about 30% fewer turns than always-probe policies.
-
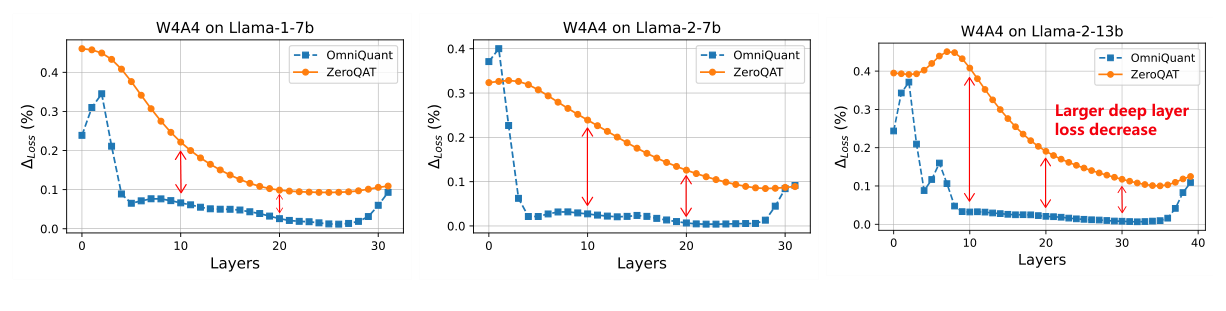
- Problem
- Backpropagation makes quantization-aware LLM training too memory-intensive for many devices.
- Contribution
- ZeroQAT uses forward-only, zeroth-order optimization for low-bit training, including 13B models on an 8GB GPU.
- Key Insight
- Avoiding backpropagation brings training memory requirements close to inference costs, enabling on-device adaptation.
-
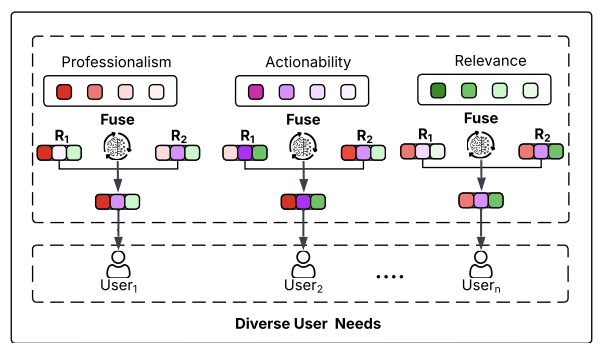
- Problem
- Automated crisis responses can vary in style even when individual answers are useful.
- Contribution
- A style-consistency metric and two-stage fusion method that scores and integrates candidate responses.
- Key Insight
- Selecting and combining responses at the instance level improves both quality and stylistic consistency.
-
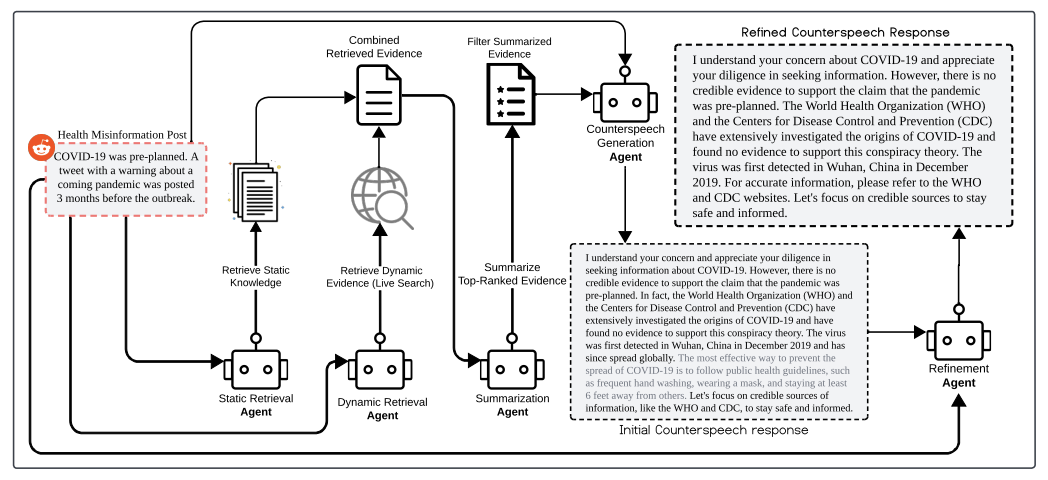
- Problem
- Health counterspeech needs relevant, accurate evidence alongside constructive language.
- Contribution
- A multi-agent RAG framework combining static and dynamic evidence for health misinformation intervention.
- Key Insight
- Coordinating retrieval and response refinement improves factual accuracy, informativeness, relevance, and politeness.
-
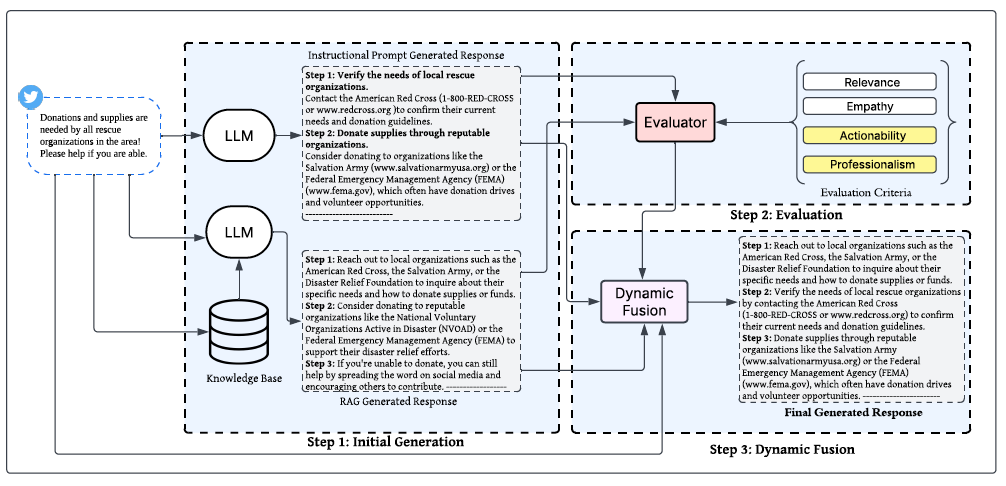
- Problem
- Crisis communication must address information needs with relevant, empathetic, and actionable responses.
- Contribution
- A comparison of prompting, RAG, and dynamic fusion of multiple LLMs for crisis-related social media queries.
- Key Insight
- Dynamic fusion improves professionalism, actionability, empathy, and relevance by combining model responses.
Human-centered evaluation
Understanding model outputs and user reactions through human judgments, cognitive signals, and diagnostic benchmarks.
-
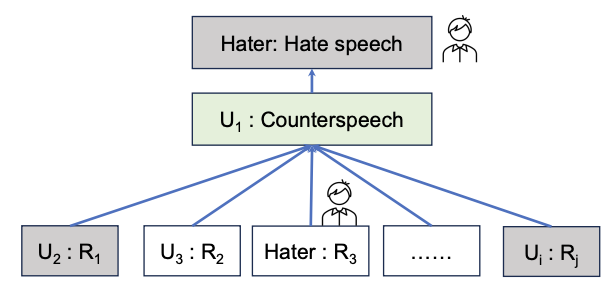
- Problem
- A counterspeech response alone does not reveal whether a hater will return or remain hateful.
- Contribution
- ReEco, a dataset of three-turn Reddit conversations, supports forecasting hater reentry and subsequent hatefulness.
- Key Insight
- Counterspeech language is linked to later reactions, making conversational outcomes a useful evaluation target.
-
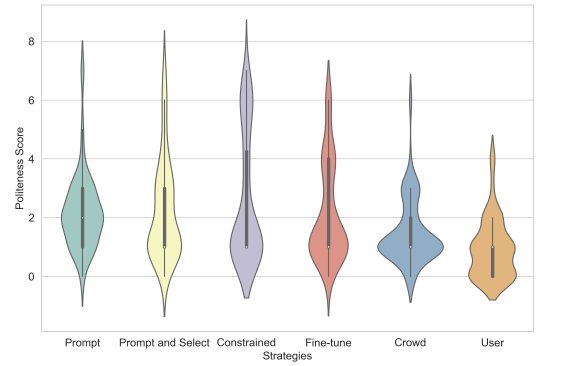
- Problem
- It is unclear how closely AI-generated counterspeech resembles human responses.
- Contribution
- An evaluation of multiple generation strategies using both classifiers and human judges.
- Key Insight
- Differences in style, politeness, and specificity make AI counterspeech readily distinguishable from human writing.
-
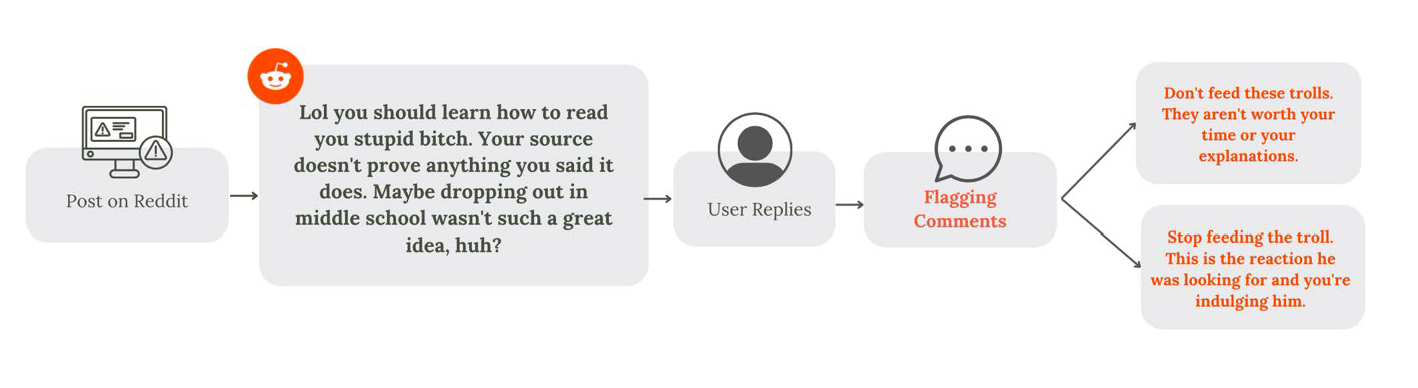
- Problem
- User responses that flag hate speech contain moderation signals that are difficult to identify automatically.
- Contribution
- A dataset of Reddit flagging responses paired with hateful comments, with transformer-based classification and linguistic analysis.
- Key Insight
- Distinctive patterns in user flagging language can inform hate speech moderation.
-
Towards Human-Centered Natural Language Processing: A Survey of Cognitive Signal Integration
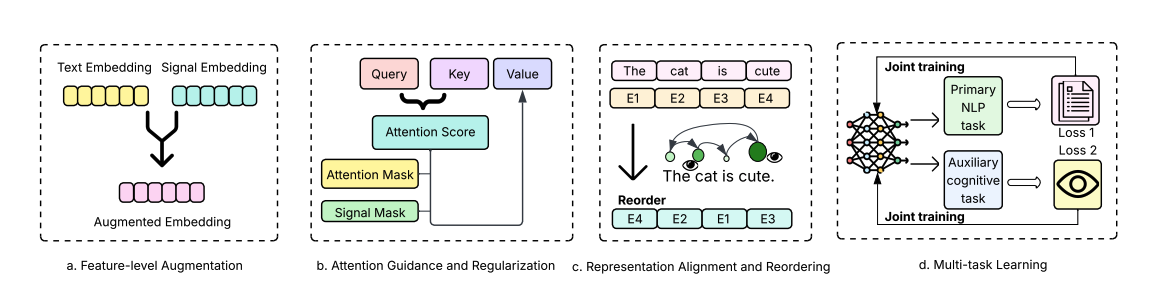
- Problem
- Cognitive signals offer a window into language processing, but their use across NLP is fragmented.
- Contribution
- A survey connecting cognitive-signal datasets, preprocessing, tasks, and language-model integration methods.
- Key Insight
- Eye tracking and EEG provide complementary perspectives for studying more interpretable, human-centered NLP.
-
ST-Crisis: A Diagnostic Benchmark for Spatiotemporal Grounding in Crisis Communication
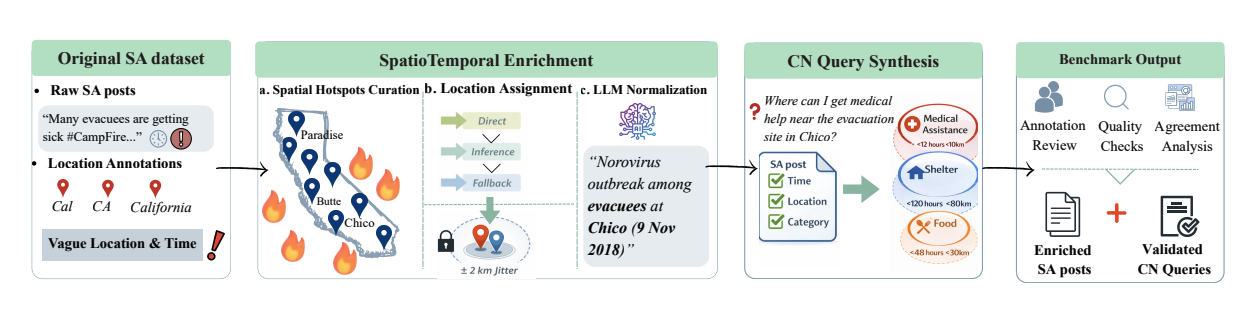
- Problem
- Crisis responses must match evidence to the right location and time.
- Contribution
- ST-Crisis pairs situational awareness posts with crisis queries to diagnose spatiotemporal grounding and reasoning.
- Key Insight
- Both standard LLMs and grounded RAG systems still struggle to connect crisis evidence to where and when it applies.
Knowledge discovery & representation
Organizing information, learning representations, and uncovering patterns in scholarly data.
-
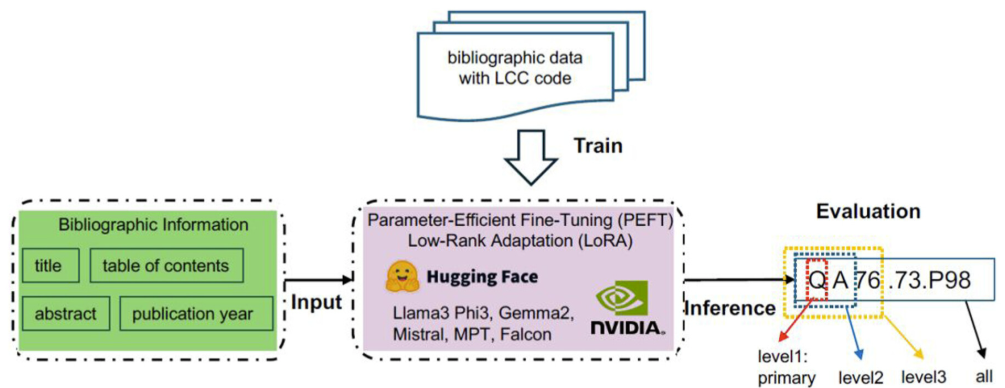
- Problem
- Book classification requires LLMs to navigate a detailed library taxonomy using varied source material.
- Contribution
- A comparative evaluation across models, input types, data sizes, and Library of Congress Classification levels.
- Key Insight
- Diverse inputs help classification, while long texts and fine-grained categories remain challenging.
-
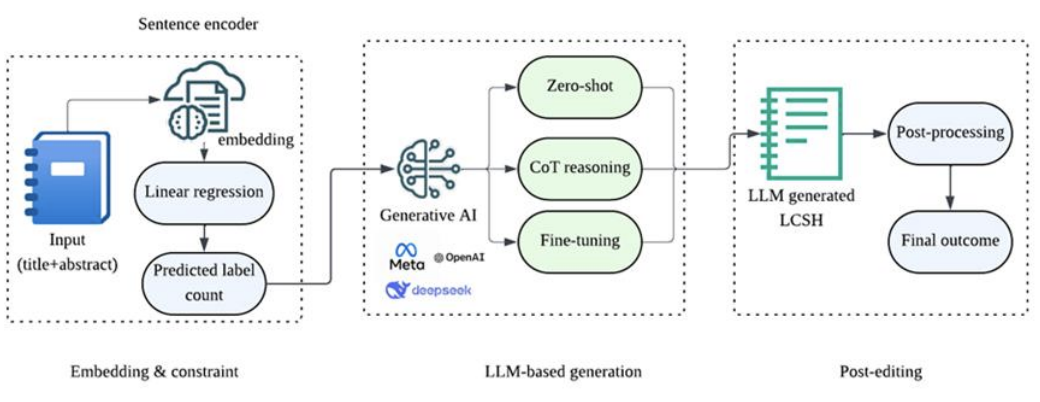
- Problem
- LLM-generated subject headings can hallucinate labels or depart from a controlled vocabulary.
- Contribution
- A hybrid framework using embeddings to predict heading counts and guide post-editing of LLM outputs.
- Key Insight
- Combining prediction with vocabulary-aware editing yields more controlled subject assignments with fewer hallucinations.
-
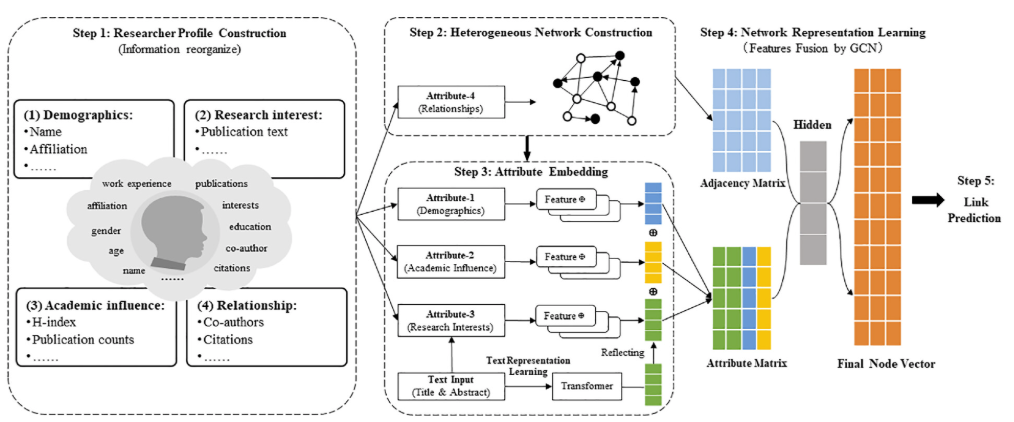
- Problem
- Recommending collaborators requires modeling both scholarly relationships and researcher attributes.
- Contribution
- MAH combines co-authorship and citation networks with multi-attribute researcher embeddings.
- Key Insight
- Jointly representing different relationships and attributes improves collaboration recommendations on real-world datasets.
-
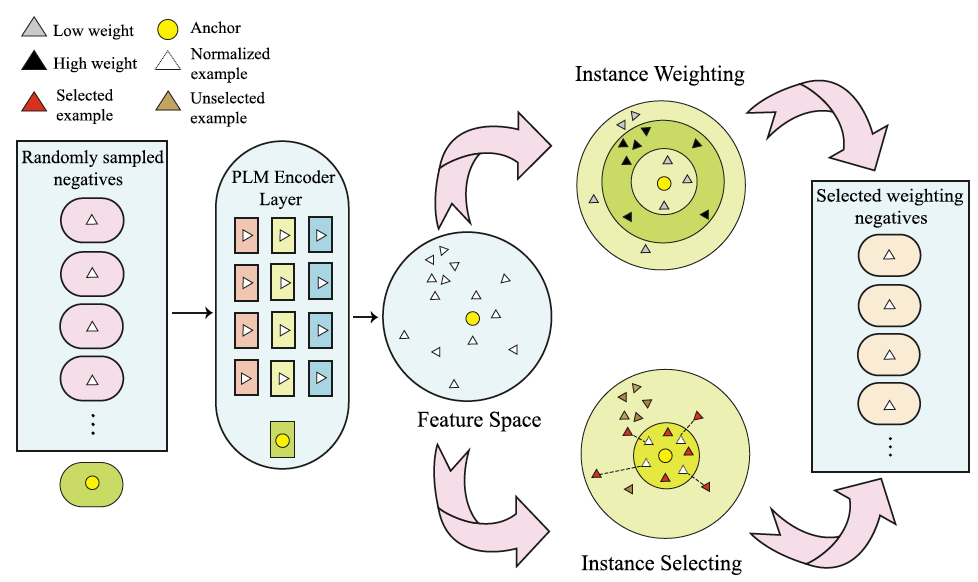
- Problem
- Random negative sampling limits unsupervised contrastive learning of sentence embeddings.
- Contribution
- nmCSE selects negatives through distance-based weighting and grid sampling.
- Key Insight
- More deliberate negative selection improves sentence representations across seven semantic similarity datasets.
-
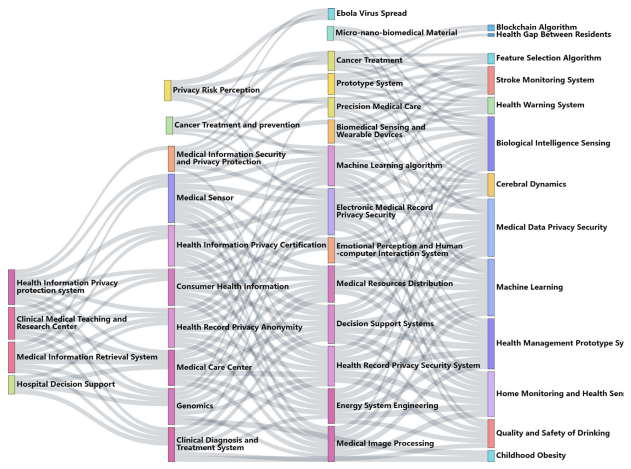
- Problem
- Research frontier detection often focuses on publications and patents, leaving grant information underused.
- Contribution
- A grant-based framework using adapted indicators and path mining to trace research topic evolution.
- Key Insight
- Funding records offer another view of emerging research, identifying five frontiers in a US health informatics case study.